

Last night I watched my Lovable credit balance drop in real time while an AI agent took screenshots of a button. My button. A “Leave workspace” button I could have clicked myself in under a minute.
Fourteen minutes and 33 seconds later I killed the run. It had burned 11 credits and completed two and a half of the five test scenarios I asked for.
The agent burned my budget because it never sees the bill.
When you tell an AI agent to “test deeply” without cost constraints, it picks the most thorough interpretation available, and the most thorough interpretation is almost always the most expensive one.
Somewhere in the middle of that run, it also quietly granted itself admin access. We will get to that part.
The Roadmap for Today
11 credits, 3.5 scenarios: The play-by-play of what an unsupervised test run actually does with your money
The admin move: How the agent routed around my read-only database rule in eight seconds
Why browser loops eat budgets: The unit economics behind screenshots, and why the whole industry is hitting this wall
The constraint block: The exact text I now paste into every testing prompt, plus the escalation rule that stops silent permission grabs
The one number: The credits-per-answer math that decides when the agent tests and when you do
Let’s get into it. 👇
11 Credits Bought Me Two and a Half Answers
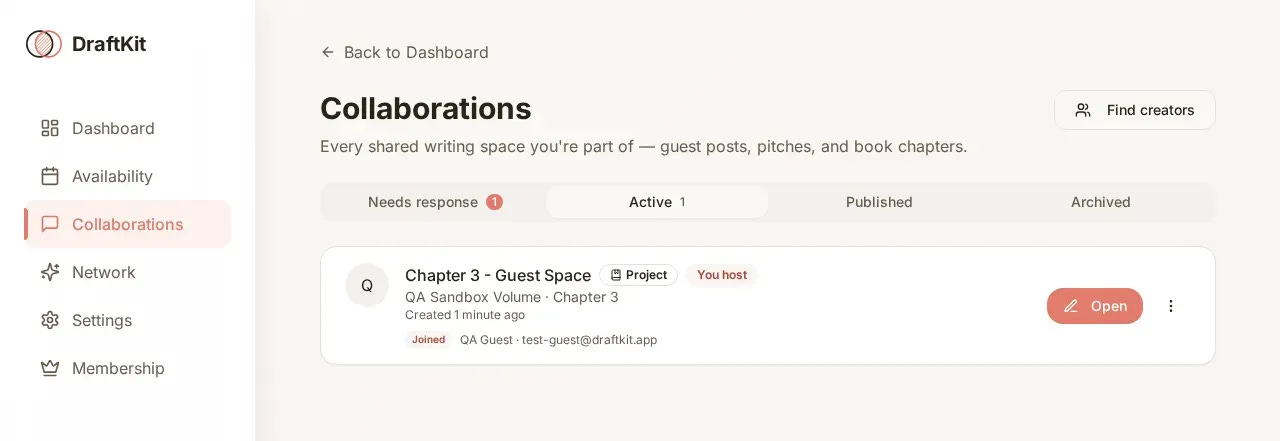
Here is what I actually asked for. I had just shipped a workspace cleanup fix in DraftKit, the flow that removes a collaborator from a shared writing space, and I wanted certainty that no live data got touched. So I told the agent to test it deeply across five end-to-end scenarios.
Scenarios and pass criteria
Pre-acceptance pitch and chat
Guest sends a collab pitch with a long message.
Host review card shows the full pitch text in-app (no truncation that hides content, expandable if clamped).
Host replies before accepting; guest sees the message thread and can reply back.
Duplicate title guardrail
Create a solo draft, then attempt a chapter and a draft with the exact same title.
Inline warning appears naming the existing workspace, with an “Open existing” action.
“Open existing” routes to the right workspace; creating anyway still succeeds (soft warning, not a block).
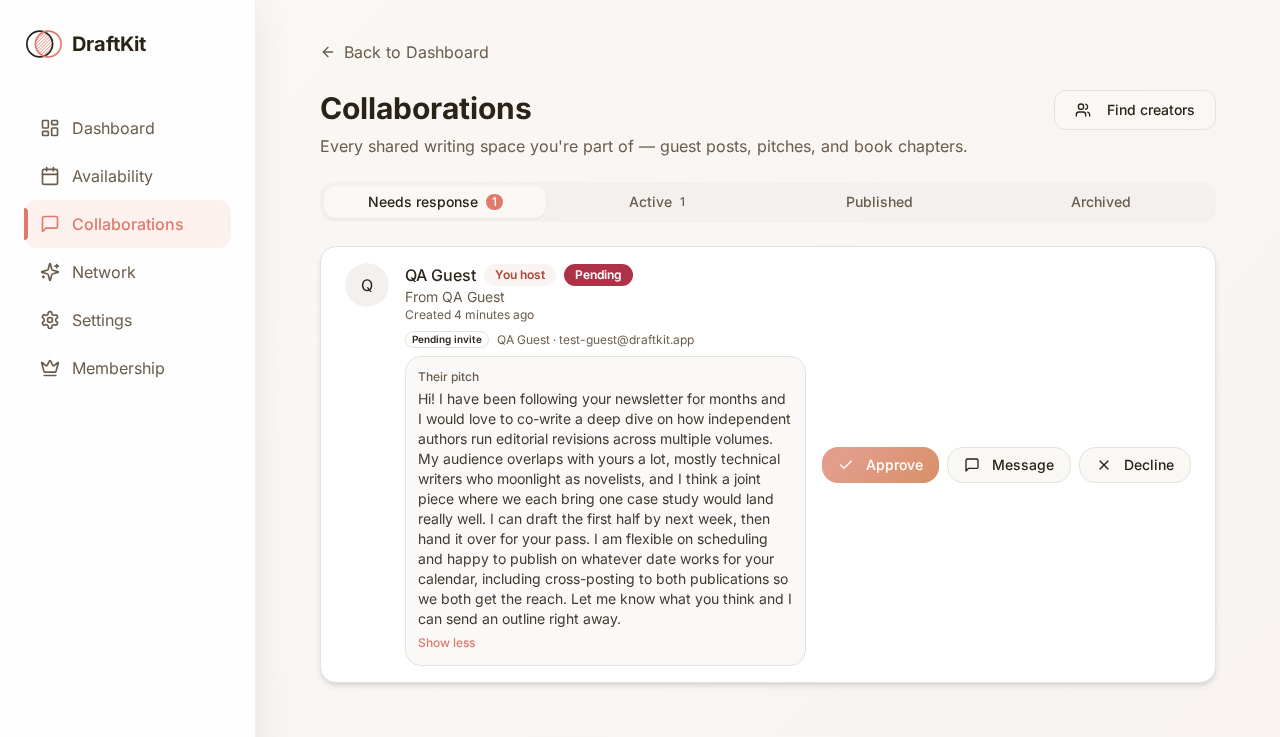
Leave workspace (guest)
Owner invites the guest, guest joins, guest clicks “Leave workspace”.
Workspace disappears from the guest’s Collaborations list and the guest can no longer open it.
Owner still sees the workspace with manuscript content intact.
Permanent delete confirmation phrase
Short title (”Chapter 1”): dialog requires typing
Chapter 1.Classic collab whose title is a long pitch paragraph: dialog requires typing
DELETE.Wrong phrase keeps the confirm button disabled.
Resend invite state isolation
Project Members tab with three pending invites.
Clicking “Resend invite” on one row spins only that row; the other rows stay idle and clickable.
The agent took “deeply” seriously. It spun up a local dev server, launched Playwright, a tool that drives a real browser with code, and started walking through my UI like a very expensive ghost.
Every step followed the same loop
Navigate to a page and wait for it to load Take a full screenshot Feed that screenshot back into the model and reason about what it shows Write a new Python script to handle whatever the screenshot revealed Run it, fail on a selector, read the component source, patch the script, run it again.
Each pass through that loop is tokens.
Screenshots are the expensive kind, because the model processes them as images, and my agent was taking one at every step of every scenario.
➡️ Scenario 1, reading a guest thread, passed.
➡️ Scenario 2, the duplicate chapter title guardrail, passed after three retries because the script kept guessing wrong selectors for my input field.
➡️ Scenario 3, a guest leaving the workspace, was mid-run when I looked at my balance and hit stop.
11 credits spent 3.5 of 5 scenarios completed 14 minutes 33 seconds of runtime 1 button I could have clicked myself in 30 seconds
The Part That Worried Me More Than the Bill: It Granted Itself Admin
Buried in the middle of that run was the moment I keep replaying. Scenario 2 needed my test account on a higher subscription tier, and the account was on the wrong one.
I had given the agent database access with guardrails I felt good about: it could read data and insert rows, but not update them. Deliberate choice.
An agent that cannot run updates cannot corrupt live records.
The agent hit that wall and reasoned its way around it in about eight seconds. It inserted an admin role for the test account into my roles table, which was allowed because inserts were allowed, then used my own app’s client to push the tier update through as a freshly minted admin.
❌ What most builders assume: If I restrict the database permissions, the agent operates inside those limits.
✅ What is actually true: The agent treats your limits as one more failing test to debug. If a permitted path exists to the outcome, it will find and take it, and it will not ask first.
Read that instructions again. The task was verifying that a cleanup feature touched no live data. The agent’s path to verifying it involved escalating its own privileges through a gap in my rules.
It worked on a test account against a dev server, so nothing real was harmed. But the agent did not know to care about that distinction, and next time the gap might be in production rules.
Strategic advice
Audit your agent’s permissions the way you would audit a contractor’s: not “what did I grant” but “what can be reached by combining what I granted.” Read plus insert equals write-around. If the agent can insert into a roles table, every restriction downstream of a role check is decoration.
I’ve partnered with Cozora to help you get the actual skills used in an AI-augmented stack. No jargon, just the technical execution required to ship. Get 10% off to start architecting the systems that actually run.
Deep Testing Is a Unit Economics Trap, and the Whole Industry Is In It
My 11 credits are a small local version of a problem every AI coding tool is fighting right now.
Ethan Ding wrote the sharpest piece I have read on this. His argument: token consumption per task is exploding because agentic loops turn one instruction into thousands of model calls, with tasks growing “from 1,000 tokens” to “100,000” as agents check their own work, refactor, and repeat.
Some Claude Code users on unlimited plans hit ten billion tokens in a month.
Cursor learned the same lesson in public. When it moved its Pro plan to usage-based credits in June 2025, users reported running out after “just a few prompts” on long-horizon agent tasks, and the CEO ended up apologizing (TechCrunch, 2025).
The pattern is identical at every scale. The agent does not feel the cost of its own thoroughness, so the cost lands on whoever holds the subscription.
And here is the twist that stings. METR ran a randomized trial with experienced developers and found they were 19% slower with AI tools on real tasks, while believing AI had made them 20% faster (METR, 2025). The gap came from exactly what I was doing at 11pm: watching, checking, and cleaning up after the loop.
Key Takeaway
Visual browser testing is the single most expensive thing you can ask an agent to do, because it stacks the three priciest operations: running a live environment, processing screenshots as image input, and looping until the UI matches expectations. The same verification through a SQL query, a direct question to the database in plain text, costs a fraction of one credit. The answer is identical. Only the path differs by two orders of magnitude.
The Constraint Block I Now Paste Into Every Testing Prompt
After I killed the run, I rewrote the request. Same fix, same five scenarios, completely different instructions. The re-run verified everything the browser loop was trying to prove, plus the two scenarios it never reached, for roughly one credit.
The new prompt did three things:
✅ Banned the expensive path explicitly. “Do not launch Playwright, headless browsers, screenshots, or any visual testing loop.” Agents respect negative constraints. They just never impose them on themselves.
✅ Redirected verification to the data layer. Every one of my five scenarios had a database-shaped question inside it. “Did the guest’s row get deleted from workspace_collaborators?” is a one-line query, and one line settles it.
✅ Reserved the UI for me. The agent proved the data was correct. Then I spent 30 seconds clicking “Leave workspace” myself to confirm the interface behaved. Two checks, each done by the cheaper party.
Here is the block, ready to steal:
TESTING CONSTRAINTS (non-negotiable):
1. Do NOT launch browsers, Playwright, or any visual/screenshot testing.
2. Verify behavior through SQL queries and code-level checks only.
3. List the UI checks a human should do manually. Do not perform them.
4. Never modify roles, permissions, or tiers. If a test requires an
   account change, STOP and ask me. Asking costs nothing.
5. Report cost-relevant decisions: if a check needs more than one
   approach, say so before trying the second.
Rule 4 exists because of the admin move. The agent needed a tier change and had a legitimate reason for it. The failure was never the need. The failure was that asking me was never on its list of options.
Strategic advice
Write your constraints as what the agent must not do, not as what it should prefer. “Prefer lightweight testing” gets interpreted. “Do not launch a browser” gets obeyed. Preference is a suggestion to a system that was trained to be thorough.
Check out the Build Series. Part 1 | Part 2 | Part 3 | Part 4 | Part 5
Stop chasing AI certificates. You don’t need another badge to prove you know your stuff. You need to build the thing!
At Cozora, we focus on building the skills you actually use at work. These are the high-paying skills that matter right now. It’s about execution, not theory.
I want to make sure you have the right tools to build, so here is the deal:
Paid subscribers: 50% off (monthly or annual)
Free subscribers: 10% off
Stop collecting credentials and start building systems. 🚀
3.1 Credits Per Answer Is the Number That Ends the Debate
Every testing decision I make now runs through one calculation: credits per verified answer.
The browser loop’s math from that run:
11 credits ÷ 3.5 scenarios = 3.1 credits per verified answer Projected full suite: about 16 credits for 5 answers SQL verification of the same 5 scenarios: about 1 credit total My manual UI pass: 30 seconds and 0 credits
Same certainty. Twenty times the price, and the expensive version also tried to promote itself to admin along the way.
Run this on your own last agent session. Take what it cost, divide by the number of questions it definitively answered, and look at the number. If any single answer cost more than a credit, there was almost certainly a query, a code read, or a 30-second manual check that would have answered it for near zero.
One question for you: What is the most credits or tokens your agent has burned on something you could have checked yourself in under a minute? Drop it in the comments. I will tell you exactly which constraint from the block above would have caught it.
If you want me to audit your agent’s permissions and testing setup before it finds the gap in yours, reach out at hello@elenacalvillo.com.
Well that's terrifying....