

Five days before a three-round panel, I opened Google Docs to start my prep.
I had three interviewers on the same link, back-to-back: a QA manager, a peer product manager, and a hands-on dev engineer. Three people, three completely different definitions of what a good AI PM looks like, 45 minutes each with no break.
A Google Doc was not going to solve that problem. I closed it and opened my code editor instead.
Two hours later I had a split-screen HTML app: color-coded interviewer cards on the left, my STAR answers mapped per person in interactive accordions, and a sticky sidebar on the right with every number I needed cold, my opening line for each call, and a three-step formula for hypothetical scenarios. I used it as a live reference all week and had it open on a second screen the day of the panel.
That is the approach I want to break down today. Not how to study harder. How to build your way into a panel instead, and the exact prompt that generates the tool for you in one run.
AI PM interview prep should produce the same output as everything else you build: something functional, personalized to the user, and faster to navigate under pressure than anything you could memorize.
Key Metrics / Context:
Lenny Rachitsky‘s March 2026 State of the Product Job Market: over 7,300 open PM roles globally, up 75% from the 2023 low and up nearly 20% since January. “Demand for AI engineers and AI PMs is similarly exploding.”
Paweł Huryn at The Product Compass: “Most PMs default to CIRCLES. You shouldn’t. AI PMs think differently.” The model recommended by OpenAI’s product lead maps intent, cognitive tasks, and agent architecture — none of which fit a behavioral STAR story.
The market is real and growing. The evaluation frame most companies are still using is not built for what builders have actually shipped. And the prep approach that closes that gap is not studying. It is building.
The Roadmap for Today:
Why the standard prep structure fails you: The specific mismatch between how notes are organized and how panels work.
The panel intelligence app: Every element and why each one was a product decision.
The case study tool: A different format, a different problem, the same builder logic.
What changed in the room: Three rounds, three different outcomes.
The prompt: The full code block you can run in Claude today.
Let’s get into it. 👇
Hey, I’m Elena! 👋
AI Product Manager, builder, and founder of DraftKit.app and the AIAdventChallenge.com. I write Prompt-Led Product, a newsletter for PMs who are tired of just writing requirements. This is for the product leader who wants to actually ship. The kind where you stop managing tickets for a second, open a prompt, and build the logic yourself.
Built by you. Led by your product taste. 🚀
If you’re new here, welcome! Here’s what you might have missed:
Join a community of PM builders from companies like Reforge, Product School, OpenAI, Lovable, Pendo, and Miro shipping AI products.
Notes Are Organized by Story. Panels Are Organized by Person.
The problem with standard interview prep is not the volume of content. It is the data model.
Notes are organized by topic: the latency story, the stakeholder story, the failure story. Panels are organized by person:
a QA manager who cares about deployment risk,
a peer PM who wants to evaluate culture fit,
a dev engineer who speaks in inputs and outputs.
Those two structures do not map to each other under pressure.
❌ What standard prep assumes: Study enough stories and you will recall the right one at the right moment.
✅ What actually happens: With three rounds back-to-back, each person asking different questions from different professional instincts, your memorized list becomes noise. You either over-explain trying to cover all your bases, or you miss the underlying question entirely because you are running a search in your head instead of having a conversation.
I had years of real work behind me: enterprise AI at scale, a latency fix that dropped response time from 4 seconds to under 1 second by redesigning the output contract from prose to structured JSON, adversarial break sessions that caught model hallucinations before Fortune 500 clients ever saw them, an architecture pivot that moved 14 million users off a locking SQL table onto event-driven messaging.
The receipts were strong.
The notes version of that work was still wrong. Not because the content was bad, but because notes are organized by what I did and panels are organized by who is evaluating me. Those are different taxonomies.
💡 Strategic advice: The gap in AI PM/PM builder interview prep is not content. It is translation. You have the work. The problem is that a QA manager reads the same story differently than a dev engineer reads it. A panel intelligence app solves the translation problem once, at build time, so you are not solving it in real time during the call.
I Built a Panel Intelligence App. Here Is Every Design Decision.
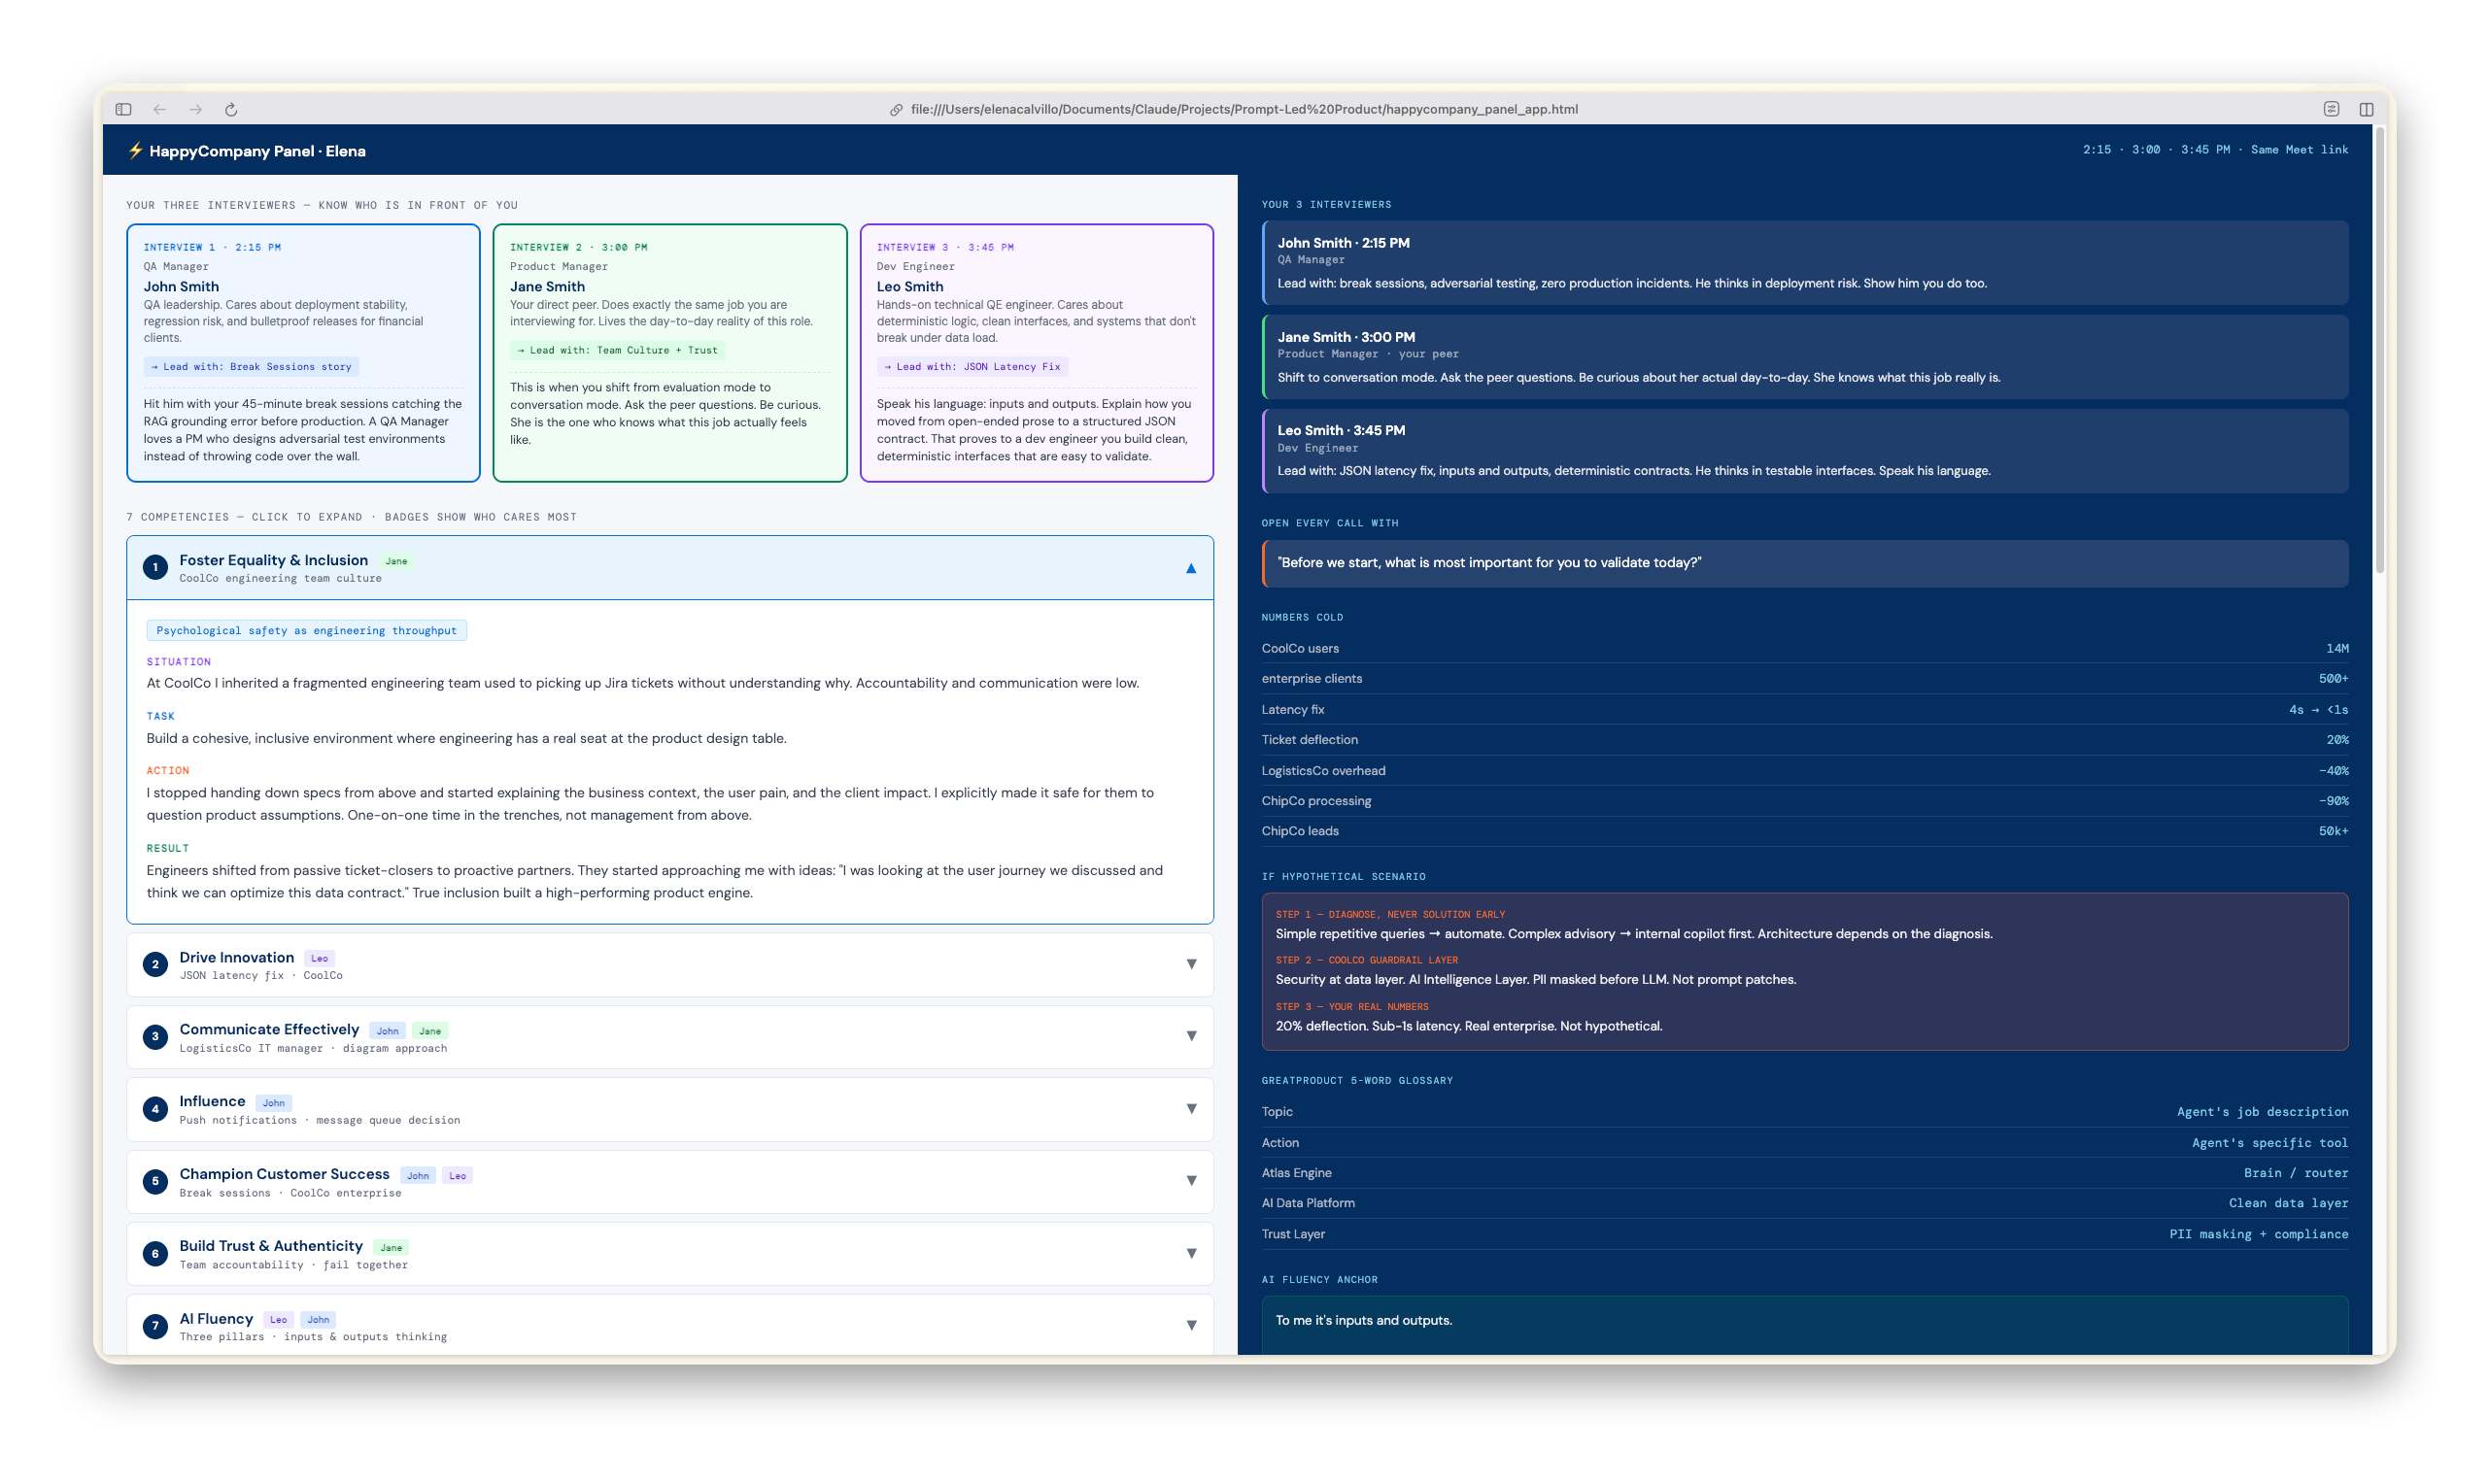
The three-round panel had a fixed structure I knew in advance. I used that structure as the product spec for the app.
➡️ Interviewer cards at the top. Three cards, each a different color. Each card had the person’s role, what they were professionally focused on, which of my stories to lead with, and a one-sentence tip on why that story lands with this specific type of evaluator.
➡️ The color assigned to each interviewer carried through the entire app: every accordion tagged to them used their color, every sidebar block used their color. When I was in round two and wanted to check something, I did not have to read labels. I scanned for the color.
➡️ Competency accordions below the cards. Seven competencies mapped to the evaluation criteria for the role. Each accordion header showed which interviewer cared about it most, tagged with their color badge. Opening the accordion showed my pre-loaded answer: situation, task, action, result, already written at the right technical altitude for that audience.
The QA manager’s version of the innovation story emphasized deterministic output contracts and regression prevention. The dev engineer’s version of the same story emphasized the input-output redesign and the latency numbers. Same underlying event. Two different translations, already loaded, already tagged.
➡️ The sidebar. A sticky right-side panel with: all three interviewers and one-line reminders of their focus, the opening question I wanted to use at the start of every call, every metric from my past work that might come up (just the number and the label, scannable in under two seconds), the three-step hypothetical formula, and a product vocabulary table mapping the platform’s terminology to the equivalent things I had already built.
The closing question was at the bottom of the sidebar: “What would make you confident I am the right person for this role?” Same question, every call, last thing on the list.
What did I learn? 🤔
Every design decision in the app was a product decision with a user in mind. The color-coding exists because I need to scan, not read, under pressure. The pre-loaded translations exist because I have 45 minutes per call, not 45 minutes plus think-time.
The sidebar metrics exist because blanking on a number mid-sentence is recoverable if you can glance down in half a second and it is not recoverable if you have to search a document. Building for yourself is still building for a user. That user is you, under pressure, in a meeting you cannot pause.
For the Case Study, I Also Built Two Things.
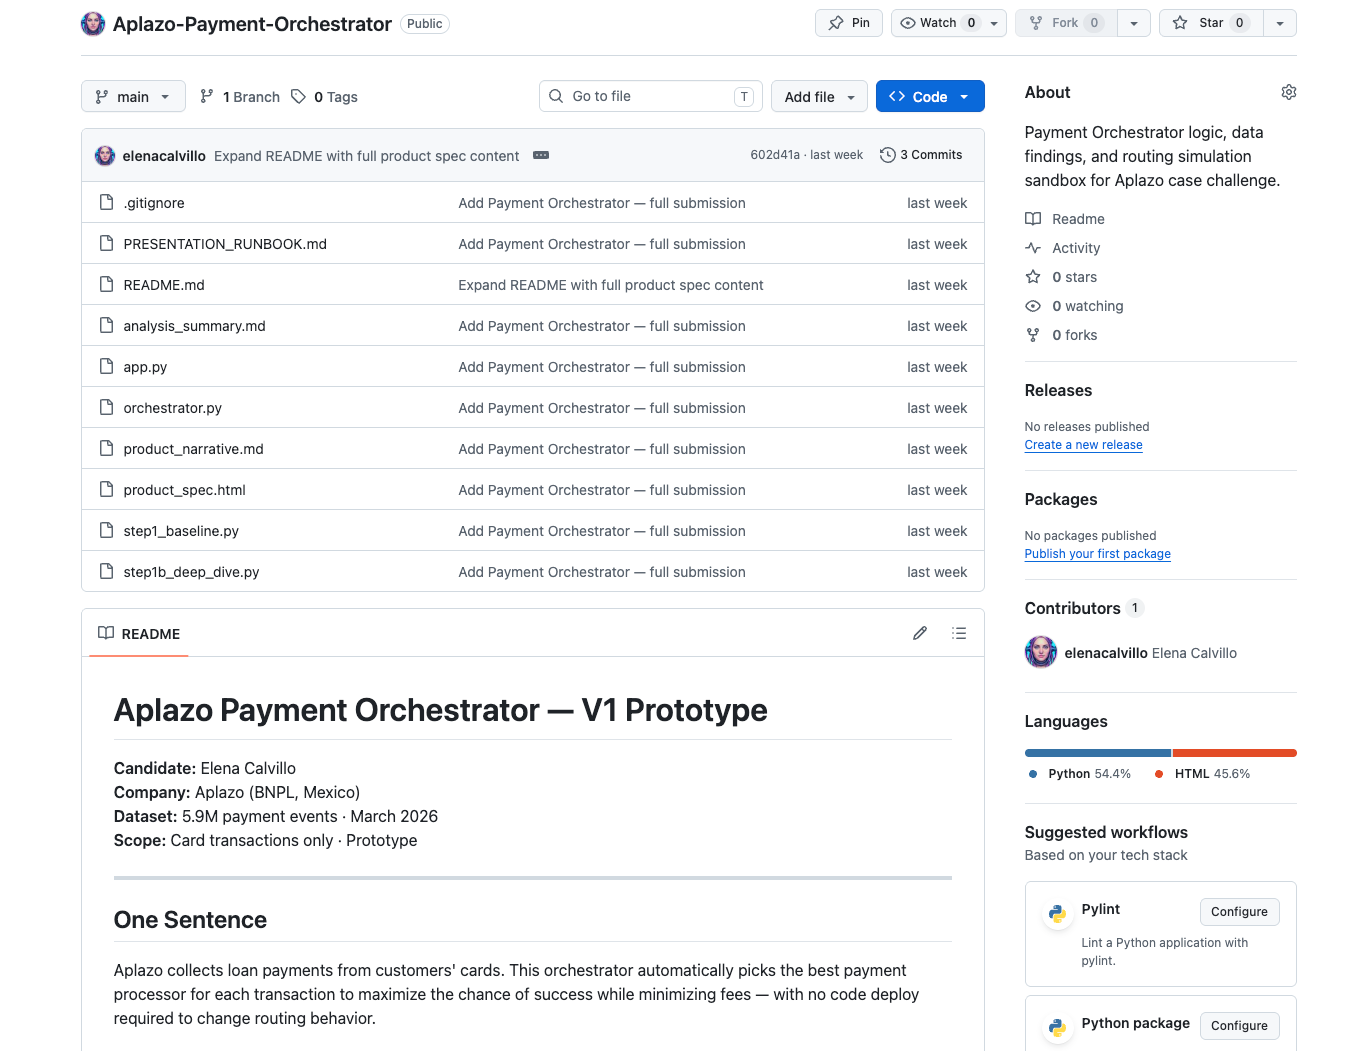
A different interview format showed up a few weeks earlier: a technical case study where I was given access to a large dataset and had to analyze it, build a prototype, and present a recommendation to a product and technical leadership team.
This is not a behavioral panel. It is a live demonstration of whether you can do the actual job.
I built the prototype and published it publicly so the panel could inspect the code themselves. The prototype was their deliverable.
But I also built a second tool, just for me: a compact accordion app I kept open during the presentation itself.
What was in the case study tool. Three data story cards: the key findings from the analysis I most needed to tell, each one framed as a non-obvious insight rather than a data summary. One stat grid with the four numbers I had to have cold. A section called “The uncomfortable questions I am going to ask them first” — three technical questions I had spotted in the data that showed I had gone deeper than the surface. The business logic behind my routing rules, organized the same way I would write a product spec.
❌ What most candidates do in a case study presentation: Prepare slides. Rehearse the narrative. Hope no hard questions come up in the Q&A.
✅ What the case study tool does differently: It is not a presentation. It is a navigation system. When the panel asks a hard question, you are not searching your memory for the answer. You are opening the section you pre-built for exactly this question and speaking from it.
The presentation went the same way as the panel: not searching for talking points, just navigating a tool I had already built and understood. The questions they asked were not surprises. I had anticipated most of them and pre-loaded the answers.
💡 Strategic advice: For a case study or technical presentation, build two things. The prototype is for them — it proves you can do the work. The reference tool is for you — it proves you can defend the work under pressure.
Most candidates only build the first one. The second one is what separates someone who shipped from someone who can also explain why.
What Changed in the Room — Three Rounds, Three Different Moments
The first round with the QA manager was the cleanest.
He asked me to walk through a production failure. I described the adversarial break sessions: 45-minute sessions where I had operations teams try to break the AI agent before it reached enterprise clients. First session caught a model returning the wrong benefit structure when a parent company had subsidiaries with similar names. Caught in prototype. Fixed before anyone in production ever saw it.
He did not ask a follow-up. He said: “That is exactly the kind of thing we look for.”
That is the moment I want you to notice. Not applause. Recognition. The panel recognizing their own production problems inside your answer. That is what the tool made possible — his story was already mapped to his color, already loaded at his altitude, already waiting.
The second round with the peer PM was the most useful.
Her card in the app said: “Shift to conversation mode. Drop the evaluation posture. Ask what the job actually feels like.” I had built that instruction for myself and it changed how I walked into the call. I opened with: “Before we start, what would be most important for you to validate today?” And then I listened.
She told me something real about what the role actually involved day-to-day. The app was irrelevant for those 45 minutes. But having it there had already shifted my posture going in, because I had already given myself permission to stop performing and start talking.
The third round with the dev engineer was the most technical.
His card said to lead with the JSON output contract story: the 4-second latency bottleneck at a previous company that I fixed not by adding compute but by redesigning the output format. From natural language prose to a structured three-field JSON response. Latency dropped from 4 seconds to under 1 second instantly. His card had one tip: “Speak in inputs and outputs. He thinks in testable interfaces.”
I opened with the latency story exactly the way the card framed it. He immediately said: “Can you walk me through how you decided what fields to include in the JSON?” That was his version of the QA manager’s recognition moment.
He was not asking about the outcome. He was asking about the design decision. The app had already told me he would care about exactly that.
What did I learn? 🤔
Three rounds on the same link are not three identical interviews running in sequence. They are three different evaluations that require three completely different postures. The peer interview is not a break between two technical rounds — it is the one that tells you whether you actually want the role. If your prep treats all three the same, you will perform the same mode across all three and miss the most important conversation in the loop.
Check out the Build Series. Part 1 | Part 2 | Part 3 | Part 4 | Part 5
The Prompt That Builds This for You
Here is the prompt I reconstructed from the app’s structure. Drop it into Claude, fill in the brackets with your panel details and your own stories, and it will generate the full split-screen HTML tool in one run.
Build me a single-file interactive HTML panel intelligence app I can use as a live reference during a back-to-back interview day. I want to open this on a second screen or my phone during the calls.

---

PANEL STRUCTURE

I have [NUMBER] interviews on the same call link, back-to-back:

Interview 1 — [TIME]
Name: [INTERVIEWER NAME]
Title: [EXACT TITLE]
What this person cares about professionally: [2-3 sentences — e.g. "QA manager focused on deployment risk, regression prevention, and whether PMs design adversarial test environments"]
Which of my stories to lead with: [STORY NAME]
Why this story lands with this person: [One sentence]

Interview 2 — [TIME]
Name: [INTERVIEWER NAME]
Title: [EXACT TITLE]
What this person cares about: [2-3 sentences]
Which story to lead with: [STORY NAME]
Why: [One sentence]

Interview 3 — [TIME]
Name: [INTERVIEWER NAME]
Title: [EXACT TITLE]
What this person cares about: [2-3 sentences]
Which story to lead with: [STORY NAME]
Why: [One sentence]

---

COMPETENCIES THEY WILL EVALUATE

For each competency, I am giving you my raw STAR. Format each one as an accordion panel. Tag each competency with which interviewer cares most using a colored badge — use each interviewer's assigned color consistently throughout the entire app.

Competency 1: [NAME]
Relevant interviewer(s): [NAME(S)]
S: [Situation]
T: [Task]
A: [Action — include specific technical decisions and why]
R: [Result with numbers]

[Repeat for all competencies]

---

PLATFORM OR DOMAIN VOCABULARY I NEED TO INTERNALIZE

Build a vocabulary table with three columns:
- Their term
- Plain English meaning
- My equivalent from past work

[TERM]: [their definition] | My equivalent: [what I built that maps to this]
[Repeat]

---

HYPOTHETICAL SCENARIO FRAMEWORK

If they give me a hypothetical product problem, I want a 3-step card sequence:

Step 1 — [NAME, e.g. "Diagnose before solutioning"]
What to say: [Exact framing or quote I can adapt]
Why this shows senior thinking: [One sentence]

Step 2 — [NAME, e.g. "Address the risk or compliance concern"]
What to say: [Framing using my real background]

Step 3 — [NAME, e.g. "Close with my real numbers"]
What to say: [Specific metric-based close]

---

NUMBERS I NEED COLD

[METRIC LABEL]: [VALUE]
[METRIC LABEL]: [VALUE]
[Repeat — these go in a scannable sidebar list]

---

SCRIPTS

Opening line for every call: "[Your line]"
Closing line for every call: "[Your line]"
Personal one-liner: "[Your positioning statement]"

---

DESIGN REQUIREMENTS

- Single HTML file, no external dependencies except Google Fonts (DM Sans + DM Mono)
- Split-screen: left side for content, right side for sticky quick-reference sidebar
- Assign each interviewer a distinct color. Use that color consistently on their card, on accordion tags, and in sidebar blocks
- Interviewer cards at the top: role, interview slot, what they care about, story to lead with, one-line tip
- Competency accordions below: color-tagged per interviewer, STAR pre-loaded inside, interactive open/close
- Hypothetical framework as a 3-step card sequence with styled quote blocks
- Vocabulary as a clean three-column table
- Sidebar: interviewer list with one-line reminders, opening script, numbers cold, hypothetical mini-guide, vocabulary glossary, closing script, one-liner
- Sticky header with panel name and interview slots
- Clean, fast to scan under pressure, professional
What you get: a functional HTML file you open in any browser, load on your phone or second screen, and navigate during the actual calls. No login, no cloud, no latency. Just your own tool running locally.
For the case study format, run a second prompt: same structure, but replace the competency section with your key data findings, the non-obvious insights you want to highlight, the hard questions you plan to ask the panel, and the business logic behind your recommendations.
The Uncomfortable Truth About How PMs Prepare
Paweł Huryn put it directly: “Most PMs default to CIRCLES. You shouldn’t. AI PMs think differently.” The framework problem he is naming in the interview room is the same problem I ran into with prep. Both the interview format and the prep format were built for a different kind of PM.
The market Lenny Rachitsky is tracking — 7,300+ open PM roles, AI demand “exploding” — means the volume of opportunities is real. What is not real yet is the universal ability of companies to evaluate the kind of PM who has actually shipped AI products. That gap does not close by performing frameworks better. It closes by making your actual work visible at the right altitude for the right person.
The two-hour build is the prep.
👨🏻💼 The PM who uses standard prep: Runs STAR stories in the same order regardless of who is in the room. Over-explains to the QA manager, under-demonstrates to the dev engineer. Leaves the peer interview feeling like a wasted slot. Exits not knowing whether the panel saw what they needed to see.
👩🏼💻 The PM who builds their prep: Maps each interviewer to the specific work signal they are looking for before the call. Walks in with the right story at the right altitude for each person, already loaded and tagged. Uses the peer interview to find out whether the role is worth taking. Navigates under pressure instead of searching under pressure.
The diagnostic: Before your next panel, answer this in one sentence for each interviewer: what is the one production problem this person deals with every day, and which story from your real work answers it? If you cannot answer that before the call, you are doing general prep. General prep is the same as showing up with a resume. They have already read that.
Run the prompt. Build the tool. It takes two hours. It changes everything in the room.
One question for you: Have you tried building any kind of tool for your interview prep, or are you still working from notes and documents? Drop it in the comments. I will tell you exactly how I would structure the app for your specific panel.
100% build. Your confidence is so much more solid.
Building a live reference app for the panel is a strong signal in itself. On the practice side, full disclosure, I built allthingspm.app, a free AI PM course from 604 job postings with JD-based mock interviews, so you can pressure-test those STAR answers before the day.