

The fastest way to lose a Lovable session is to type “make it better.” The model has no idea what “better” means to you. It rewrites what it thinks you want, overwrites what was already working, and you spend the next 45 minutes undoing good work to undo one bad change.
That loop is not an AI problem. It is a communication problem, and this prompt structure is the fix.I hit this wall building a PM skill-assessment app inside Lovable. The first version came together in about 40 minutes. Then I started refining it.
The feedback I was giving was genuine but vague: “the layout feels off,” “this section should be cleaner,” “the button placement is wrong.” Every note triggered a cascade.
By session two, Lovable had reorganized the entire component tree trying to interpret what I meant. I had a broken product and a frustration I had created myself.
The moment I switched to the CLEAR method, the drift stopped. I finished that app, shipped it, and it now serves 900+ users across the Prompt-Led Product ecosystem.
FYI, CLEAR method is a structured framework used in software development to write clear, actionable bug reports and feature requests.
Why Vague Feedback Breaks AI Builders Faster Than Bad Code
Lovable is not reading your mind. It is pattern-matching your words against its training data to generate the most probable response. When your instruction is “fix the layout,” the model picks a layout interpretation. It might be right. It is often not.
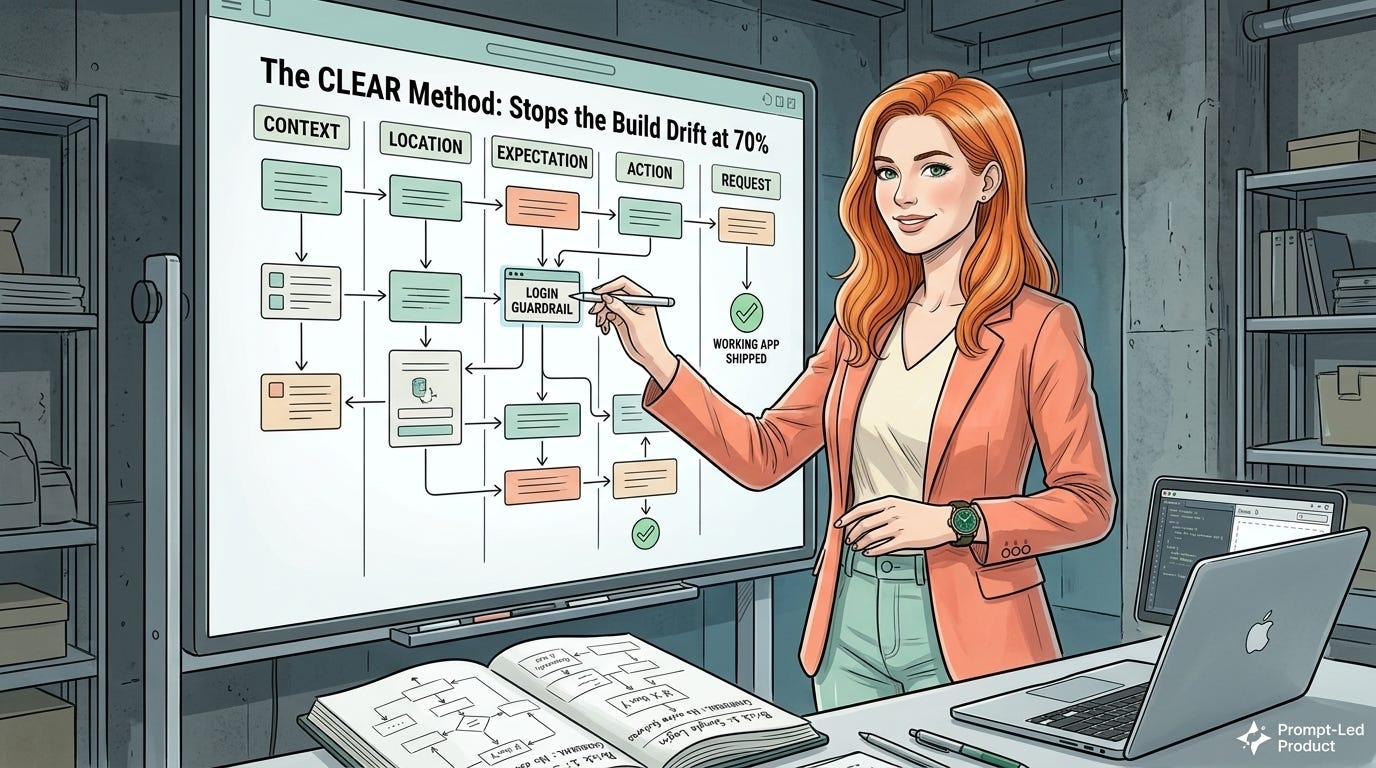
This method gives the model exactly five pieces of information it needs to make a precise change without touching anything else. Each piece narrows the solution space.
Precision is the only currency AI accepts.
The five parts:
Context (why you need the change),
Location (the exact page or component),
Expectation (what it should do),
Action (what it is currently doing wrong),
Request (the specific fix).
The Prompt Logic Behind CLEAR
Most debugging prompts are missing the Location and Action fields. You tell the model what you want but not where the problem lives or what the current wrong behavior is. Those two gaps force the model to guess. When it guesses wrong, you correct it again, and the correction triggers another cascade.
CLEAR locks the scope of every change to one element at a time. The model cannot drift because you have given it a precise coordinate: this component, this behavior, this fix. No interpretation needed.
The opening architecture prompt sets the foundation before any code is generated, which prevents a different class of failure: scope creep from the model. Starting with five features and explicit user context keeps the model anchored to your product, not its own interpretation of what a generic app should look like.
The Prompt
[THE OPENING ARCHITECTURE PROMPT]
"I want to build a [type of app] called [app name]. The main purpose is to [one sentence description]. Here are the core features I need: 1. [Feature 1] 2. [Feature 2] 3. [Feature 3] 4. [Feature 4] 5. [Feature 5]. The target users are [user type]. Let's start with a simple version and I'll give you feedback as we go. Can you create the basic structure first?"

[THE CLEAR METHOD FEEDBACK TEMPLATE]
"I want to [Context]. On the [Location - specific page/section], it should [Expectation]. Instead it is [Action]. Please change it to [Request]."

[THE MOBILE OPTIMIZATION PROMPT]
"Optimize this specifically for mobile users: 1. Ensure all tap targets are at least 44px. 2. Make text readable without zooming. 3. Test that all interactions work with touch. 4. Verify the layout adapts correctly to screen sizes from 320px to 428px wide."
The checklist that goes with this:
✅ Define the 1-sentence foundation before you open Lovable
✅ Apply the 5-feature limit, iterate only after the base structure is live
✅ Execute the CLEAR method for every refinement, no exceptions
✅ Run a success audit: functionality, mobile responsiveness, error handling
How to Run It in Lovable or Claude
Start with the Opening Architecture Prompt before you generate a single component. Copy the template, fill in the brackets, and submit it as your first message. Do not skip this step. The model’s first response sets the entire architectural pattern for the session.
For every refinement after that, use the CLEAR template. Fill in all five fields. If you cannot fill in the Location field, you are not ready to give the feedback yet. Find the exact component first, then give the note.
The mobile prompt runs after the core layout is stable, not before. Optimizing for mobile mid-build creates conflicts between the responsive rules and whatever layout the model was building. Sequence matters.
Find More Prompts Like This
This prompt is part of the Prompt-Led Product Vault, a growing library of battle-tested prompts I use when building AI products, auditing existing ones, and leading technical PM decisions.
Every prompt in the Vault comes with useful examples, the logic behind the structure, and a real usage example.
Why This Is a Competitive Advantage for PMs
Most PMs treating Lovable like a magic wand will hit the 70% wall. They get a working prototype fast, then spend three times as long trying to refine it because every feedback loop introduces new errors.
CLEAR turns you from a reactor into an architect. You are not responding to what the model does. You are directing exactly what it does next.
In 2026, the barrier between an idea and a shipped URL is 60 minutes if you can describe the logic precisely. That is the skill. Not knowing Lovable. Not knowing React. Knowing how to communicate intent with enough precision that the model never has to guess.
If you want me to help you implement this inside your actual product stack or audit your current Lovable build for CLEAR method gaps, reach out at hello@elenacalvillo.com.
I stopped typing two of those five. Context and Location live in a file the model reads every turn, so what I actually type is the Request. Took me a while to work out where things go: anything true everywhere in one file, anything about a single tool in another.